

An introduction
Recently we’ve seen a ton of movement in the market with consolidation and it almost begins to sound like a broken record. However — data quality, trust, speed of delivery, and value are bigger problems than ever. Data Teams are getting cut. More is being asked of Data Teams. Executives want data faster. Data Platform Teams are now AI and Data Platform Teams. So there is more work than ever to be done, and paradoxically, we seem to have less hands albeit more tokens to do it.
ELT, or specifically EL (extract and load) remains a critical part of the stack. Every enterprise data engineer I speak to is principally concerned with moving data, replicating databases, and replicating data across regions.
However, there is some light forming. API connectors are now so easy to build, you can just get AI to write the code for them, leaving infrastructure as the missing piece.
Database replication remains something that is gnarly. One of the final challenges or “ELT FINAL BOSS” might be cross-region replication across different buckets in different cloud providers in different regions; that’s really exciting stuff.
In this, I want to cover a bit about how setting up pipelines means you now need best-of-breed to really feel like an “AI-Enabled engineer”. What is best of breed? Well — certainly not an all-in-one platform.
There is a growing divide between those who “simply do everything in Fabric”.
These people are willing to accept that Microsoft has the biggest fist in the room, and consequently are happy to have their orchestration, monitoring, and ELT subsidised by their extortionately priced Power BI licenses.
Databricks to an extent are in the same category, though Databricks is a better product.
Snowflake want to be in that category, but put simply Snowflake Tasks, Snowflake dbt, Snowflake Horizon, OpenFlow etc. are inferior products to their Databricks counterparts, and far inferior to those things on the market specialising in their niche.
So perhaps it makes sense to have a complex architecture with Fivetran, dbt Cloud, Apache Airflow, Kubernetes, Datadog, Monte Carlo, Atlan, Cube.dev and Tableau?
Perhaps not — such a combination is rather expensive, and rather hard to stitch together. Let’s face it — there’s a lot of overlap between those tools that were all once heralded as “Best of breed” but they’re not anymore. Why not?
It is telling that companies like Informatica, that used to be best of breed, no longer are because they are “too clunky”. The same is said for companies like Matillion, though they have a new CEO and a ton of new hires, which should tell you something.
Fundamentally these companies offer three things
Data movement
Some form of data transformation
Some limited alerting and orchestration / scheduling
The biggest missing piece in all of this? An enterprise orchestrator. The biggest and #1 time-sink for companies without an orchestrator operating at scale is building, fixing, debugging, and answering questions stakeholders have of “where is my data” and “Why isn’t this fresh?” — the answer as you all know — is a lack of orchestration, and a lack of observability.
Best of breed is no longer the categories that the Modern Data Stack gave us. Best of breed for me at least, now encompasses a few smaller categories
Data Movement and Data Replication
Data Storage and Compute
Control Plane (Orchestration + Observability + Metadata + incident management + runtime for agents)
It is no surprise to see Fivetran and dbt pitch themselves as everything you need. They did this last year.
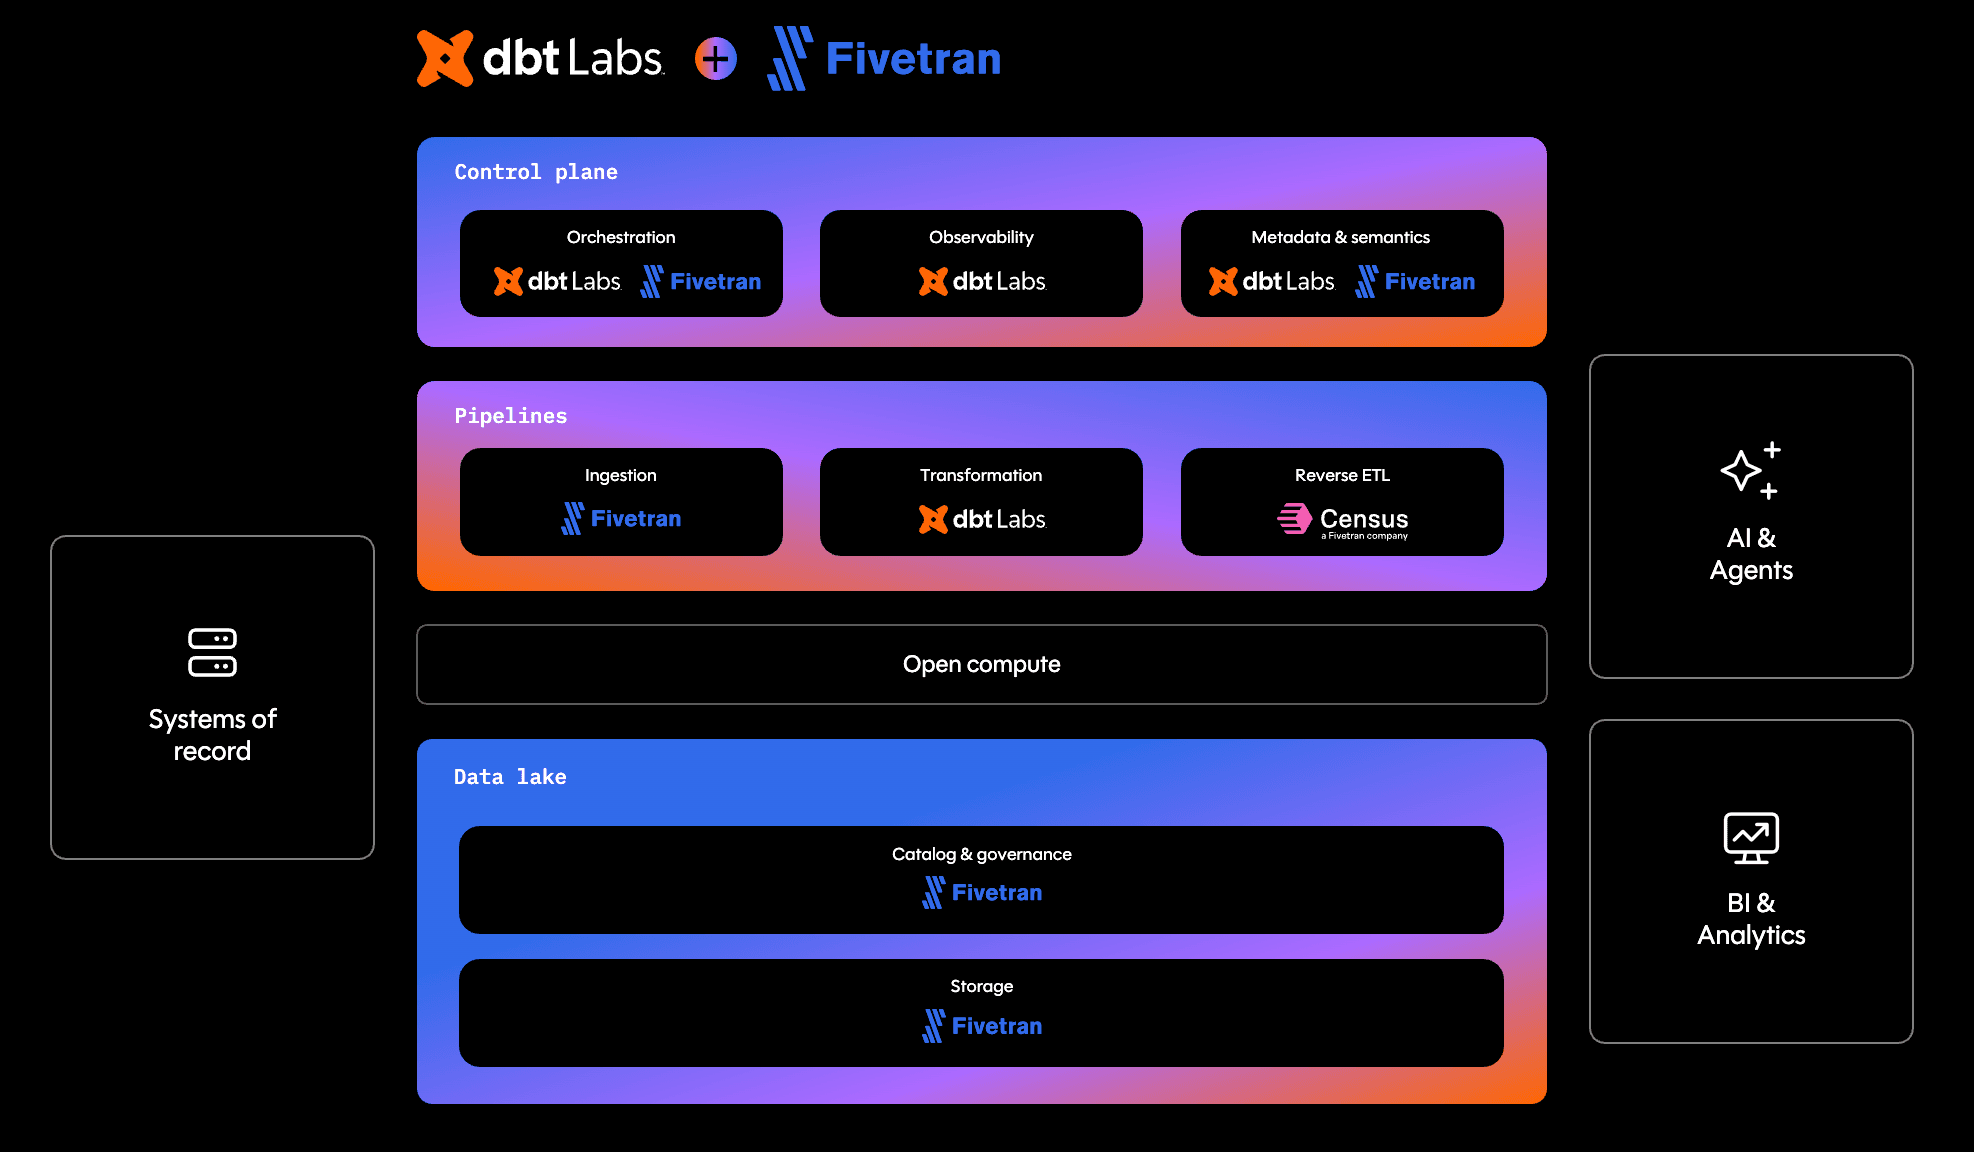
This was the same pitch as Informatica, Matillion and lo! The trend is coming back.
Apart from you us data engineers have memories, and they’re short but not that short!
Further examples and reading lifted from last week - skip to the end for conclusion
Example: How to build an ELT Pipeline end-to-end using AI with Estuary and Orchestra
Orchestra does can move data using python and it transforms data using dbt. It is a baby step in ELT; where you use Orchestra to run python to move data before graduating to a managed ELT tool.
Its main job is to decide whether the next thing should run, given the state of everything upstream of it. That framing sounds narrow until you notice that most of what upstream consists of is software we did not write and cannot inspect from the inside.
This means the interesting engineering in an orchestrator is almost entirely about integrations. Every one we ship is an answer to a specific version of the same question: how does a scheduled task find out whether the system it depends on is in a state worth depending on.
Daniel Pálma at Estuary recently built a pipeline that made this concrete enough to write about, and the result is a good illustration of why I think about integrations the way I do.
The setup: postgres CDC to Snowflake using Estuary
Postgres CDC into Snowflake through Estuary, running continuously. On top of that, an Orchestra pipeline running daily: dbt build, then four Snowflake data-quality tests. Seven tasks, scheduled.
The whole thing was authored by agents using two skill packs, ours and Estuary’s, against live accounts. It took nine runs to go green. Five of those nine runs failed at the same place, which is the part worth talking about.
The gap that best-of-breed opens up: streaming
Traditional orchestration assumes discrete work. A job starts, does something, exits with a code, and the orchestrator reads that code to decide what happens next. The model is clean because the boundaries are clean.
A streaming CDC pipeline has no boundaries of that kind. It is always running. There is no exit code, and there is no moment at which it declares itself finished. So when a daily dbt build wakes up and reads a warehouse table that a streaming pipeline has been writing to for the last twenty-four hours, it has no principled way of knowing whether that table is trustworthy.
This is the new best-of-breed. You need to basically just assume that data is getting streamed and replicated in real-time, especially if it’s db stuff. There is less stuff to orchestrate, but no less stuff to monitor.
Takeaway #1: streaming reduces the need for orchestration but increases the need for observability
In practice teams close this gap by writing a Python task that calls an API, parses a response and raises an exception. I have seen that task written many times. It is written slightly wrong most times, usually because the person writing it picked the first available signal rather than the right one, and because the failure semantics were decided in a hurry.
That pattern is exactly the shape of thing an integration should absorb. So ESTUARY_CHECK_FLOW takes four parameters:
check_capture:
integration: ESTUARY
integration_job: ESTUARY_CHECK_FLOW
parameters:
task: dani-demo/agent-demo/source-postgres
error_threshold: 0
warn_threshold: 0
latency_threshold: 1800
connection: ${{ ENV.ESTUARY_CONNECTION }}
It reads the Estuary task’s OpenMetrics endpoint and compares deltas against the previous check. New logged failures above threshold, or latency above threshold, and the task fails. No transaction progress, and it warns.
Read metrics, not liveness for observability
The first design rule I hold integrations to is that a check has to tell you something you could not have learned from a ping.
A liveness endpoint tells you a process is up. That is close to useless as a precondition, because the failure mode you actually care about is a pipeline that is running and not making progress. logged_failures_total, txn_count_total and publish latency are the signals that distinguish those two states, and reading deltas rather than absolutes is what makes them meaningful across scheduled runs.
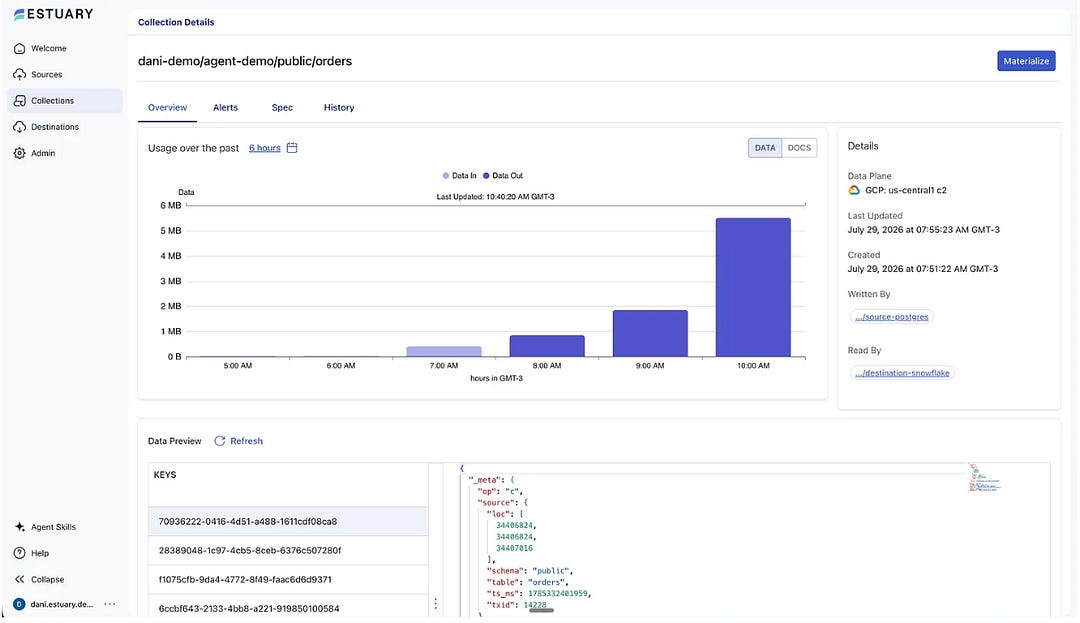
There is a cost to this precision, and Dani found it. Our latency metric measures commit acknowledgement, so it reads in the hundreds of seconds even when Snowflake is nine seconds behind Postgres. A threshold set from a data freshness SLA will false-alarm continuously. That is on us to document better, and the practical advice is to tune the threshold against the metric you are actually reading.
Takeaway #2: observability and visibility is critical for streaming pipelines which are best-in breed, but it needs to be combined with visibility of batch pipelines
Three states, because infrastructure is mostly degraded
The second rule, and the one I would defend hardest: a health check needs three outcomes rather than two.
Binary checks force an unpleasant choice. Make them strict and they block good runs on transient noise, which teaches your team to ignore or remove them. Make them permissive and they let dbt build models on stale data, which is the failure they existed to prevent. Neither version survives contact with real infrastructure, because real infrastructure spends most of its life somewhere between fine and broken.
So WARNING allows downstream tasks to proceed and FAILED blocks them. A materialization syncing slowly warns and the batch layer runs. A capture that is throwing connection errors stops the line.
Dani’s run 4 is the clearest evidence that the semantics are right. Both Estuary checks came back WARNING, the pipeline continued, and dbt then failed on its own unrelated credential problem. The gate did not hide that failure and did not manufacture one.
The AI was able to understand all of this and explain it to me, because Orchestra had a lot of the metadata and context about the Estuary and dbt runs together anyway.
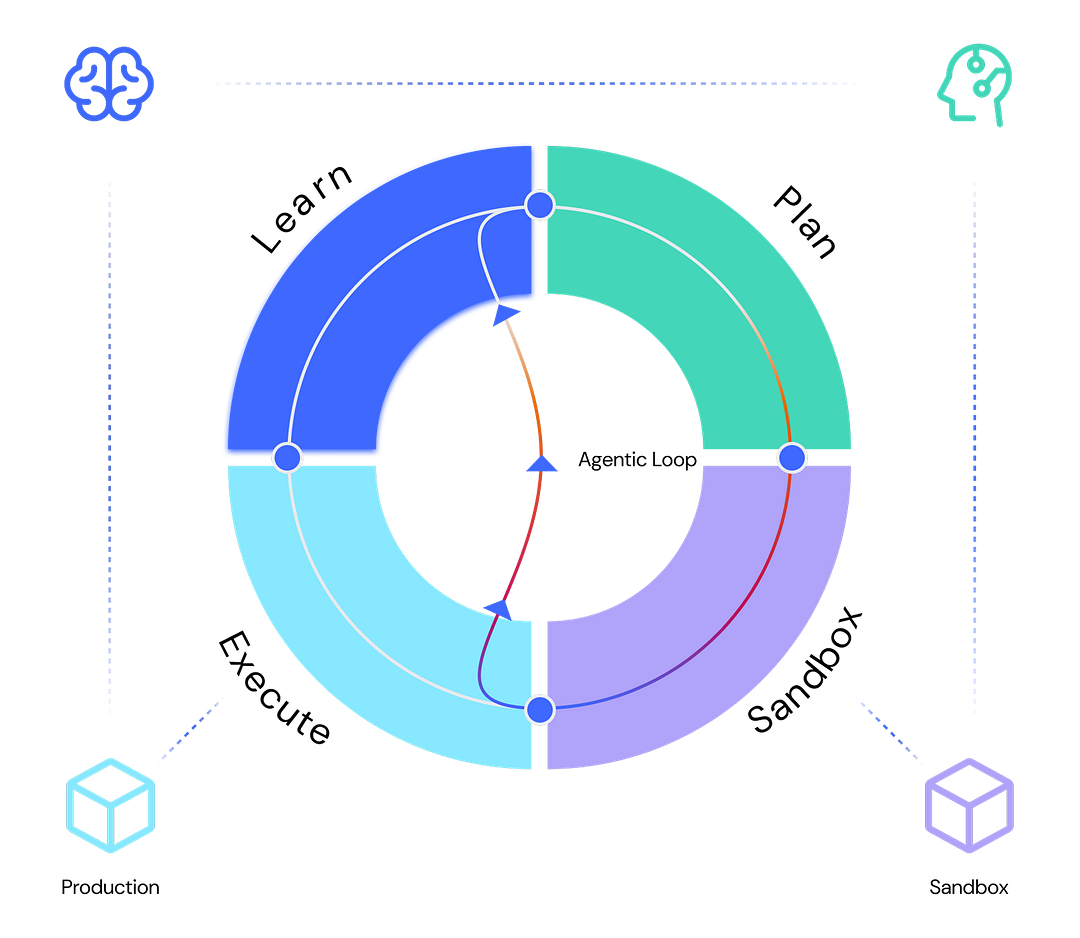
This leads to:
Takeaway #3: context and agents about pipelines are critical for building AI data Engineering resources
Preconditions belong in your control plane
Most people describe orchestration as running things in the right order. The framing I find more useful is that an orchestrator enforces conditions.
Data quality tests are postconditions. They run after a transform and tell you whether the output is acceptable, and everyone already accepts that they belong in the pipeline. Health checks are the same idea pointed the other way. They run before a transform and tell you whether the input is acceptable.
Both are cheap, both are declarative, and both should be visible in the same lineage view as the work they guard. When a precondition is buried inside a Python task, nobody can see why the pipeline stopped without reading code. When it is a task in its own right, the run history answers the question directly.
These are not separate concepts that require separate tools. They’re just things you should be able to do in a modern tool.
What agents changed about how we build APIs
Both skill packs in this build are agent-facing, and ours act through roughly 28 MCP tools rather than a CLI, because orchestration state lives behind an API rather than in files on disk.
The lesson I took from watching an agent use them was not about authoring. Agents write first-draft YAML badly. Across the two products Dani’s first drafts had six schema errors, including one of ours:
422: Invalid parameters for DBT_CORE_EXECUTE: commands - Input should be a
valid string, input_type=list
That error is the useful part. It names the field, states the expected type, reports what it received, and costs nothing to trigger, because validate_pipeline runs in seconds and writes nothing. An agent reads that and fixes it. A vaguer error, or an expensive one that only surfaces after publishing and waiting for a run, would have stalled the loop.
Which reframes something I used to think of as developer courtesy. Specific errors and free dry-run validation are now the difference between an API an agent can iterate against and one it cannot. If you are building anything with a public API right now, the strictness of your validation layer is a feature, provided the messages are precise about what went wrong.
The same holds for diagnosis. The agent found the bug in run 6 by pulling logs through three MCP calls, and the log filename gave it away before it read any content:
“1/dbt deps dbt build — select stg_orders daily_order_metrics”
One command where there should have been two. Reading that correctly is a more valuable capability than generating the YAML in the first place.
Takeaway #4: with AI, everything must be controlled as code or editable via API/CLI so they can be agent managed
Where this still needs a human
Worth being precise, since the story is partly a story about automation. Agents authored, published, diagnosed and fixed everything. A human was required for exactly three steps, all of them credential handling: creating the Orchestra connections, minting a GitHub read token, and supplying Snowflake credentials that Estuary encrypts and never hands back.
Connections being UI-only is the one I think about most. There is a real tension between making credentials scriptable and making them safe to hand to an agent, and I do not think the industry has settled it. Mapping existing connections to environment variables is already automatable through update_environment. Creating them is deliberately not.
The main takeaway is to go best-of-breed or suffer
The reason to run tools like Estuary and Orchestra together is that streaming health becomes a first-class precondition for batch work, expressed in four parameters and visible in the same lineage as everything it guards.
Five of nine runs in this build ended with the gate refusing to let dbt read the data. A demo that goes green on the first attempt tells you nothing about whether your preconditions are load-bearing. This one told us they are.
AI was used to generate everything and debug everything which was incredible to see. Everything was controlled as code. Everything you need for a best-in-class experience was handled with just three tools — Estuary, Orchestra and Snowflake.
Dani’s full technical writeup, including the gotcha catalogue and the demo repo: HERE
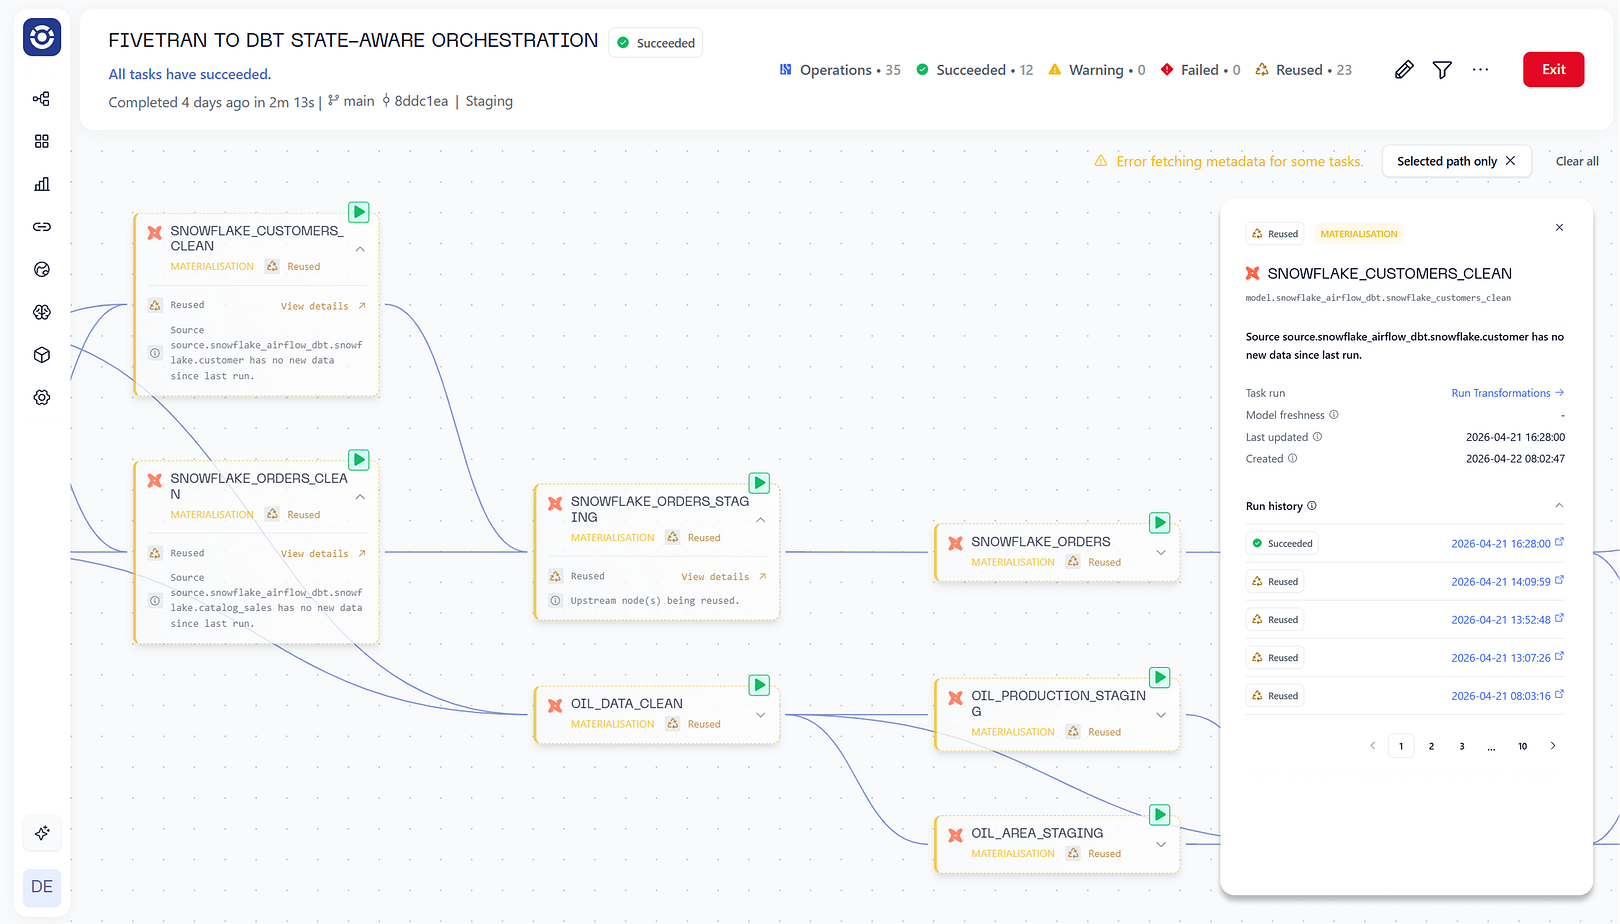
ALSO don’t forget — nice features like state-aware orchestration make everything REALLY easy to schedule. State means you can just run the same job over and over again — you don’t even need to have it in the same pipeline, since it won’t run anything erroneously that doesn’t have new source data; as the orchestrator catches the state.
This can help teams go incredibly far. It even scales to multiple teams, with both Estuary, Orchestra and Snowflake supporting multiple deployments for multiple teams across multiple regions.
The other point is scalability. I genuinely believe this is scalable as hell, since there is no infrastructure to maintain, no connectors to maintain, and everything can be automated on the maintenance side using AI. This is something I’ve never seen before as a data engineer, and it’s truly incredible to see with many shared customers like Trust&Will and Raylo leveraging Orchestra alongside Estuary to be best of breed.
Best-of-breed have to better and cheaper than the incumbents to make a business case. Those that can do it will be the best teams, with the least funding pressures. There aren’t many companies like that so when you find them act fast!
HL
Hi Hugo,
actually, it’s been like this since 1996:
Extract - from all sources
Land - Land data into the landing area
Load - Load the landing area data Into the staging area (later than 1996 we created delta detection)
Transform - coming out of the staging area using views
Land - the staging area data into the work tables between staging and DWH for better failure recovery
Load - Insert/Update data from the work tables into the data warehouse
Anyone who wants to see the SQL that gets generated for how we do this can get it from my freebies link. We have a fully worked examples.
Of course, this processing has evolved over the last 30 years. What we do now is better than 30 years ago. But its the same processing done better ways. Today this can be done 100% in SQL though we also use C++ programs to do this for dimension tables in multi-level models.
The whole ETL / ELT thing is really more to present where the Transformation processing happens. Some products choose to try and do “T” in the data warehouse itself. This has advantages and dis-advantages just like having a staging area and doing the transformation in views coming out of the staging area.
Lastly, all the software I discussed above is free and open source. Anyone can have it and use it. It is my ETL software circa 2012. Men can also “go to school” on it when selecting their production ETL software.
I wish you a good day.