

Introduction
One of the biggest announcements from dbt Coalesce 2025 was state-aware orchestration. It was incredible to see a large number of practitioners interested in learning more about what is a pretty technical topic — orchestration.
However, to think that this is a new concept or that storing state is a novel invention would be a mistake.
State has existed in recent areas before such as dlt, sqlmesh, and even one of Orchestra’s competitors who shall of course remain unnamed. However the concept is much older — spark uses state to allow spark structured streaming to work. Iceberg metadata is just state.
Chat GPT offers a brilliant insight into the list of technologies that use state (scroll to the end of the article to see, there are dozens).**
Shockingly, some data practitioners are not interested in the idea of state-aware orchestration for SQL queries. If State-Aware orchestration can reduce warehouse costs by 64% (or is it 29%?) why wouldn’t people care?
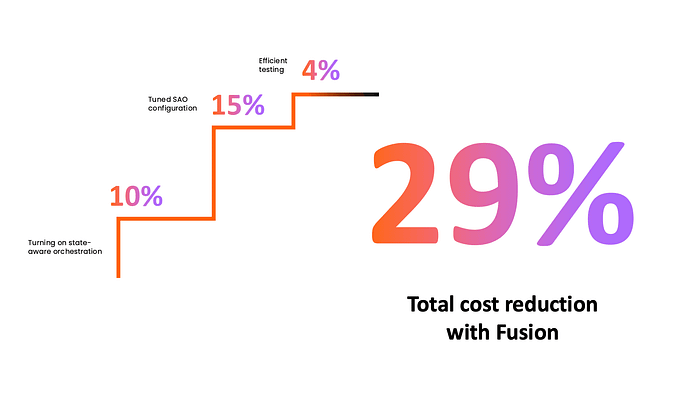
An important distinction is that stste-aware orchestration != Fusion. Fusion is more the rust compiler in my mind, but equally a banner term for the rust compiler, state aware orchestration, and any other features announced in the last 3 months
This was validated with our Orchestra customers too. Many of our enterprise users, who leverage Orchestra as a single pane of glass for orchestrating pipelines efficiently and well across massive environments were oddly not so phased by state-aware orchestration.
I felt compelled to explain why.
In this article, we will take a look at some state-aware approaches to orchestration, what “state” actually means in this context, and when and why these problems arise.
The problem: mo tables, mo problems
Imagine you have a few hundred tables and everything runs on its own schedule, no problem. Assume data lands when it is supposed to. Everything runs a dream.
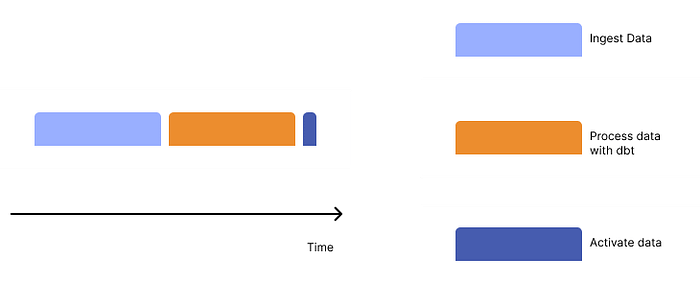
A very simple illustration of a well-functioning pipeline
Over time, you increase your tables. Schedules become oft and frequent. This leads to extra overhead since if A → B → C if you change what you want for C, you need to remember to change the tags for A and B as well.
Furthermore, let’s say you increase your team size and some people forget to turn off models. This means you may be materialising A, B and C but perhaps nobody even uses C.
Finally, let’s say data starts landing erratically. You may end up running all your models, even though there is no new data. This becomes a big problem if you are materialising tables fully.
We can distill these into a few assumptions
Data lands when it is supposed to
You do not have many schedules
Analysts do not spend a lot of time manually tweaking schedules via the dependency tree
Analysts remember to remove old models
When you run your models, you run them incrementally
Take off these assumptions, and you might need state aware orchestration.
The Solution: State Aware Orchestration from the ground up
I think about state aware orchestration in two ways.
Better dbt scheduling syntax
The first is an asset-centric way. This is what Orchestra is built for, though we haven’t done it.
Consider a simple DAG. You specify when it runs, and the orchestrator runs the tasks in order.
schedule:
  frequency: daily

tasks:
  task_a:
    type: python
    command: run_python

  task_b:
    type: python
    command: run_python

  task_c:
    type: python
    command: run_python
    depends_on:
      - task_a
      - task_b
With state aware orchestration, the yml looks a bit different.
task_a:
    type: python
    command: run_python

  task_b:
    type: python
    command: run_python

  task_c:
    type: python
    command: run_python
    depends_on:
      - task_a
      - task_b
    sla:
      - daily
The benefit here is that you do not need to move the task definitions between different pipelines or different schedules. This minimises overhead for analysts, since they do not need to worry about moving the relevant models into the relevant schedules.
You will also notice that the first code snippet is essentially the input the orchestrator needs to know what to do. If you are beady-eyed, you will also see that the first snippet can be generated from the second snippet.
This concept is not new. Informatica Power Centre has a metadata-driven version of this, so does IBM DataStage, Ab Initio, Oracle Warehouse Builder from mapping logic. The newness of data technology is not absolute but relative to your experience, it seems!
By having a better, more declarative syntax, we argue, analysts orchestrating dbt can save time on this use problem:
[3] Analysts do not spend a lot of time manually tweaking schedules via the dependency tree
This is tied to [2] as well. Let’s say you had like 15 schedules with different names. You then look at your customers table at and see
table:
  customers:
    tags: [’hourly’, ‘marketing_hourly’, ‘daily’, ‘finance_one_offs’,
           ‘business_critical’,’etc’,’etc’]
When should this run? we have no idea. So simply being able to say “hey these are the times we want this updated, go work it out” is nice as it means noone needs to waste time working out what all these undescriptive schedules mean.
[2] You do not have many schedules
Storing dbt state and table state
This is the interesting part — table state is essentially more data that says what has happened.
The simplest way to think of it is to imagine you have a table that has a column with an auto-incrementing ID or watermark. The “state” is then, effectively, stored on the table itself! Just select max(watermark) from table and you’re good!
This would result in a full table scan which could be slow and expensive, so the state is stored separately in a table resmebling {”table_1”:123, “table_2”:234} .
Instead of fully processing the data, the orchestrator should check the cache and fetch the state. For example, let’s suppose we have 500 table 1 records — without the state we will process all 500. With the state 123 we can process just the remainder (377 records). This will be faster and cheaper.
The state will then update to 500.
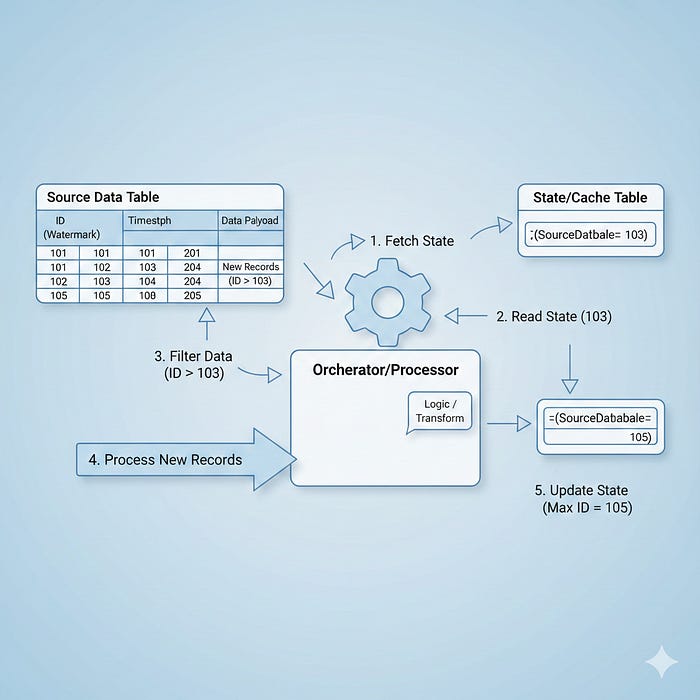
This is not a terrible illustration. But I do recommend ignoring the images and reading the captions in order.
By only running models when new data arrives, if data doesn’t land when it is supposed to then you will save money. This counters Assumption 1:
[1] Data lands when it is supposed to
It also helps counter Assumption [4] where analysts forget old models. Let’s say you do a CRM migration and now have a load of old dbt models with old data. There is no recently-arriving data for the old as the old CRM is deprecated.
With SAO these models don’t need to be manually turned off, they will just never run.
[4] Analysts remember to remove old models
Incrementality
When jobs are incremental already (Assumption 5) you could argue that storing state is not necessary. Here I lean on the arguments Tobiko made about state — essentially, storing state is just a bit cleaner and more reliable than “hoping” your incremental window fits.
[5] When you run your models, you run them incrementally
A solution looking for a problem or a mind-bending innovation?
We spend a lot of time, not just helping people build dbt projects but helping them build scalable multi-tenanted AI and Data systems. There are lots of ways you can solve these problems, state aware orchestration or SAO being one.
New Data (or lack of it) with an orchestrator
The interesting thing about state is that you also don’t need to worry about processing things if there is no new data. Even if you have an incremental daily model that fetches the last day of data, what happens if there is no new data?
In that case, you would run your incremental model anyway, and materialise everything downstream again.
Here is where Orchestration comes in.
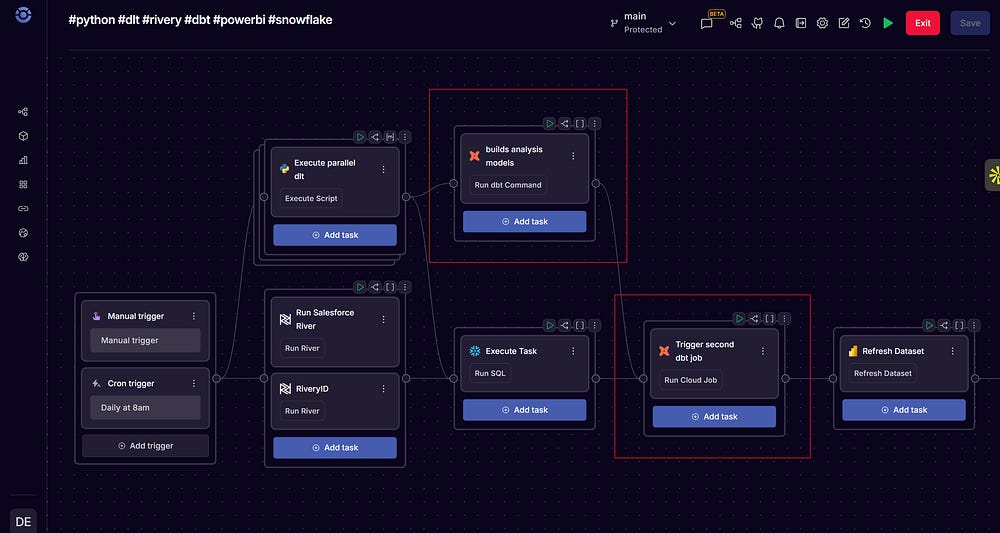
A simple dbt dag
Let’s say you have a simple end to end DAG where you are loading some data using python to a warehouse, then executing some dbt.
If you actually use an orchestrator (which you should) then the dbt will never run if there is no new data. This is because your upstream jobs should basically say “hey there is no new data, this pipeline ends in a warning state” and therefore dbt doesn’t run.
Or, they should fail, perhaps if it means you know the absence of data is something worthy of a failure. For example, let’s say you run the data team for a mature software company. In that case, if you’re not receiving any product data for a certain time period, then you can be pretty sure there is an error somewhere.
Not to mention the reason there is no new data is often not due to an absence of data, but due to an operational failure — for example, you forgot to update your code when an API changed, and now your data load is broken.
Using Orchestra with dbt Cloud or dbt Core is a KILLER pattern here.
This helps solve for:
[1] Data lands when it is supposed to
Larger organisations and sensor patterns
A common dbt orchestration pattern in larger organisations is to have a more publish/subscribe relationship between producers and consumers.
In this case, rather than orchestrate everything end to end, you might have a data engineering team that are responsible for landing data in a warehouse. An analytics team might pick that up and orchestrate it with dbt. And then finally data consumers at the other end take clean data and use it for cool stuff like AI Agents n stuff.
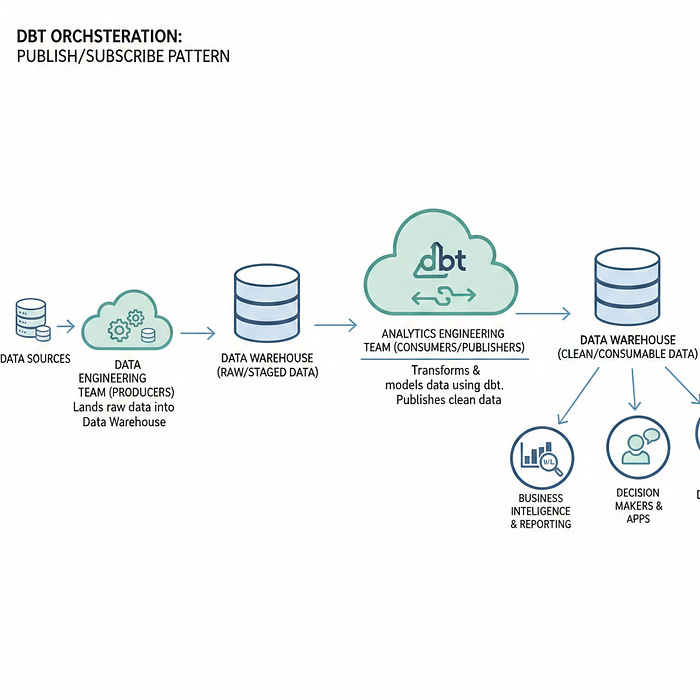
Come on Nano Banana at least finish the iamge
Do we need state aware orchestration here? It’s helpful to look at our assumptions again.
Data lands when it is supposed to
You do not have many schedules
Analysts do not spend a lot of time manually tweaking schedules via the dependency tree
Analysts remember to remove old models
When you run your models, you run them incrementally
In this case, we often see different teams providing very tight SLAs. Things simply do not run if the SLA isn’t met. We also see tighter SLAs on the producer side than the consumer side.
This is because generally engineering teams seem to be a bit more static and a bit more mature. Unless you’re constantly acquiring new businesses in say, a private equtiy or M&A context, you’re unlikely to have loads and loads of new data sources to move.
By contrast, data consumers ALWAYS want more stuff. A new dashboard here, a new piece of analysis there. Data for Marketing’s new Agent.
This means the requirements are often quite complicated. You might be able to easily bucket your sources into stuff that lands hourly and stuff that lands daily, but the SLAs of your end products could be much more varied.
How does this affect dbt? State aware orchestration is very helpful here, because you can more easily manage this disparate range of schedules.
But it’s not enough.
That’s because your downstream consumers need some level of orchestration too. Let’s say you have a nice meta config like below.
models:
  - golden_super_data:
      sla:
        - hourly
and it gets materialised hourly. Your downstream [agent/dashboard/reverseETL job] runs hourly too. But what happens if there is no new data or there is a data quality issue?
dbt State-aware orchestration occurs but the downstream consumer is left not really knowing what’s going on.
This is where a full Orchestration Platform can be really helpful. For example, let’s say you have a dashboard that depends on 4 or 5 models. With Orchestra, you can leverage a sensor to trigger that and alert you if it doesn’t successfully fire.
version: v1
name: ‘#sensors #snowflake #powerbi’
pipeline:
  61a273b3-27e4-4279-a040-b924824bc6e1:
    tasks:
      01d79f7c-5a66-457f-8c4c-62c7a24f9a47:
        integration: POWER_BI
        integrationJob: POWER_BI_REFRESH_DATASET
        parameters:
          dataset_id: Some_Id
        dependsOn: []
        name: dataset to refresh
    dependsOn: []
    name: ‘’
sensors:
  ff3b9a0c-0d50-4adf-9475-29a64cd8f236:
    name: Sensor trigger
    cron: 0 8 ? * * *
    timezone: Europe/London
    timeoutMins: 60
    checks:
      Snowflake1:
        integration: SNOWFLAKE
        sensorType: SNOWFLAKE_QUERY
        parameters:
          query: >-
            select * from table_1 where timestamp >
            dateadd(-1,HOUR,current_timestamp())
      Snowflake2:
        integration: SNOWFLAKE
        sensorType: SNOWFLAKE_QUERY
        parameters:
          query: >-
            select * from table2 where timestamp >
            dateadd(-1,DAY,current_timestamp())
webhook:
  enabled: false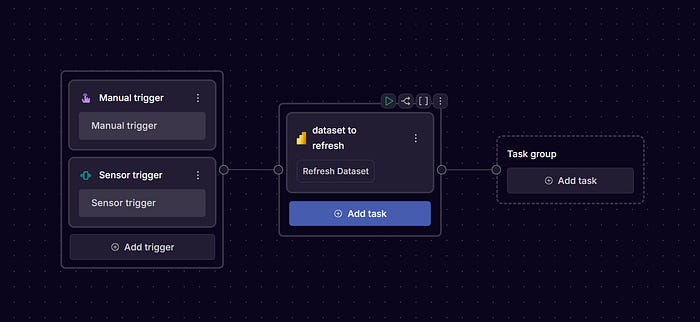
This is much more flexible and scalable than forcing downstream users to come in and learn a new orchestration framework like an Airflow, or get them to mess around with dbt exposures (which inevitably get out of date). You can also do basically anything here; run another dbt project, run an agent, run python etc etc.
Again you’re making it easier to have less schedules, have more ownership (so analysts don’t forget about stuff), and do less manual tweaking by democratising orchestration here.
Can State Aware Orchestration make you go faster?
So far we’ve identified 5 assumptions that if broken, mean state aware orchestration might be necessary for your organisation.
When models are defined incrementally, end-to-end orchestration is implemented, and quality rules around freshness are implemented, the impact of state aware orchestration may be lower.
However, at scale and without end to end orchestration these assumptions fall down.
Data often does not land when it is supposed to, leading to erroneous builds
Many schedules mean many DAGs and more complexity
Complicated DAGs mean people need to “tweak” tags on different schedules which is arduous and time-consuming
Analysts may forget to remove old models at scale / in response to a lack of new data (e.g. migrating from an old CRM to a new
old_crm_data_aggregated->new_crm_data_aggregated) — in this case there will be no new data as the old CRM is dead but you may still end up materialising all the models by accidentA lack of incremental modelling increases the cost of completely refreshing tables needlessly
Fundamentally, if data arrives on time and the dbt project is kept relatively simple, then pipelines will get processed efficiently. Simplicity and keeping tech debt minimal are SO IMPORTANT and avoiding getting in this mess in the first place should be Plan A.
However, there is one main additional point I think is really key when it comes to state-aware orchestration that’s very valuable. Esp. for people looking to go fast.
It’s all well and good saying “my data models get updated daily”. But how do you ensure data arrives at the right time? Consider:
Data lands on the hour at 1pm, 2pm, 3pm etc.
Run the data model at 1pm, 2pm, 3pm
You can see the problem immediately. If the data is delayed by a second then the data itself will always be an hour out of date. At 2pm, you’ll only have data up to 2pm, 3pm at 2pm, and so-on.
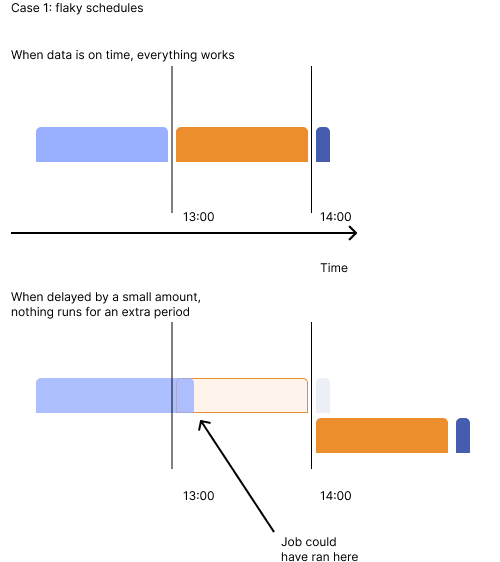
If you knew the data landed at 1.05, you could run dbt at this time and materialise the data. In that case the data itself will only have a 5 minute lag.
The answer here is to run dbt more frequently without worrying about what happens. The cache will say when there is new data, so you can run dbt every 5 minutes and this means the data can get updated more automatically.
It is almost like dbt behaves as one massive sensor.
This allows you to go faster and have tighter SLAs. Data Teams always underestimate what they need to give to gain trust. The business doesn’t need real-time dashboards, so you give them daily data. But what if all data simply was real-time? What would the business ask of you then?
Counter-intuitively, sometimes ambition is a function of what is possible, and not the other way around.
Conclusion — state aware orchestration is a compelling choice for large enterprises in a snafu
There are a few interesting observations to make here.
Should I just run dbt state aware as frequently as possible?
Yes! You should. I don’t see why you wouldn’t. Of course it means that if your parse times are slow then you could back stuff up, creating phat queues, which would be undesirable. But yes I suppose this is why you have the Rust-based parser in Fusion.
What is all this talk of “Fusion-Compliance”?
dbt Labs want everyone using the Fusion Engine (“Fusion-Compliant”) so that they can establish dbt as the open standard for data transformation. This is an important KPI, we surmise, for fundraising purposes.
Will State-Aware Orchestration replace the need for driving good data culture?
No! If you can make people send their data on time and care about data quality at source then your life will be infinitely easier and better, no matter what technology you use. You could even use stored procedures in a SQL Server!
And yes — you should also keep your data modelling projects following some basic data modelling principles and stop it becoming “spaghetti”.
Why did dbt Labs say their internal costs went down by 64% if the result for us is only 29%?
Why indeed. Perhaps models weren’t being run incrementally, perhaps they had so many models they just kept materialising stuff all the time. Perhaps Snowflake were giving them a massive rebate which meant they just ran dbt all the time with wanton abandon.
Whatever the case — It’s unlikely their internal project set-up was representative of what’s happening in the field.
If I already have a system in place, should I move to something more “state-aware”?
If that system is large (1000+ models) and complicated then probably yes.
If not, then also probably yes, though it may create a bit more scope for complexity (anyone can add any schedule to any thing, vs. everyone knowing “we have hourly data. That’s good enough for us and that’s what we do”).
How can I try dbt state aware orchestration?
State-aware orchestration is not currently supported for dbt Core. It is proprietary and not available in the open-core project. This is because dbt Cloud leverages a Redis Cache under-the-hood, the logic of which is not open sourced.
What alternatives are there to using state aware orchestration?
Try Orchestra. By orchestrating things end to end you basically never process data if there is no new data. It also encourages very good system design, so you end up taming the complexity at source instead of cooking too much spaghetti.
☁️ See how Orchestra works with dbt Cloud here
* Examples of state in historical pieces of technology
- Watermark tables / high-water-mark tables
- Checkpoint or control tables in ETL jobs
- ETL metadata repositories (Informatica, DataStage, OWB)
- Database CDC log positions (LSN, SCN, WAL offsets)
- SQL Server Change Tracking / CDC state
- Oracle GoldenGate log position state
- IBM InfoSphere CDC state
- File-based state on HDFS (Sqoop, Flume checkpoints)
- Hadoop _SUCCESS marker files
- Hive partition metadata as implicit state
- Presto/Hive partition-based watermarks
- Kafka consumer offsets
- Kafka Connect offset storage
- Airflow metadata DB run-state tracking
- Airflow XComs for passing state
- Spark Structured Streaming checkpoint directories
- Spark watermark state
- Delta Lake transaction log metadata
- Apache Iceberg snapshot metadata
- Singer tap/target bookmarks
- Meltano state files
- Fivetran internal offset/log state
- Airbyte connection-level state.json
- dbt artifacts (manifest.json, run_results.json)
- dbt state comparison (state:modified)
- dbt partial parsing cache
- SQLMesh environment snapshots
- SQLMesh model versioning state
- dltHub (dlt) incremental cursor state
- dlt JSON/DB-based state storage
- Debezium offsets in Kafka Connect
- Flink checkpoint state
- Kinesis shard iterator / sequence number state